Build with AI speed.
Ship with human-grade evidence.
ASEWAVE is a human-controlled AI software delivery method for solo developers and small teams building production systems where every claim must be verified, replayable, and backed by evidence.
AI agents can write code fast. They can also write confident fiction fast.
ASEWAVE exists because AI-generated progress should not be accepted as truth just because it is fluent. The method forces work through investigation, implementation, evidence capture, disk verification, and independent review before a phase closes.
The goal is not autonomous AI development. The goal is controlled AI acceleration with a replayable audit trail.
Four principles. One audit trail.
Wi24RD develops XDRagon Monitor using ASEWAVE — a disciplined, human-owned, AI-assisted method where every phase starts with an investigation and ends with a walkthrough tied to verifiable evidence.
Swipe sideways to see all three phases →
One human owns direction. Separate AI roles produce and challenge the work.
AI agents assist with specification, implementation and verification — but their claims must be checked against the actual codebase. Scope, prioritization and every destructive decision stay with the human.
Turns intent into structured phase prompts. Reviews investigations, challenges claims not backed by evidence. Does not write production code.
Verifies assumptions against the real repository, implements after approval, captures artefacts, and produces walkthrough evidence.
Holds scope, priorities, release decisions and every destructive operation. No phase closes without human approval.
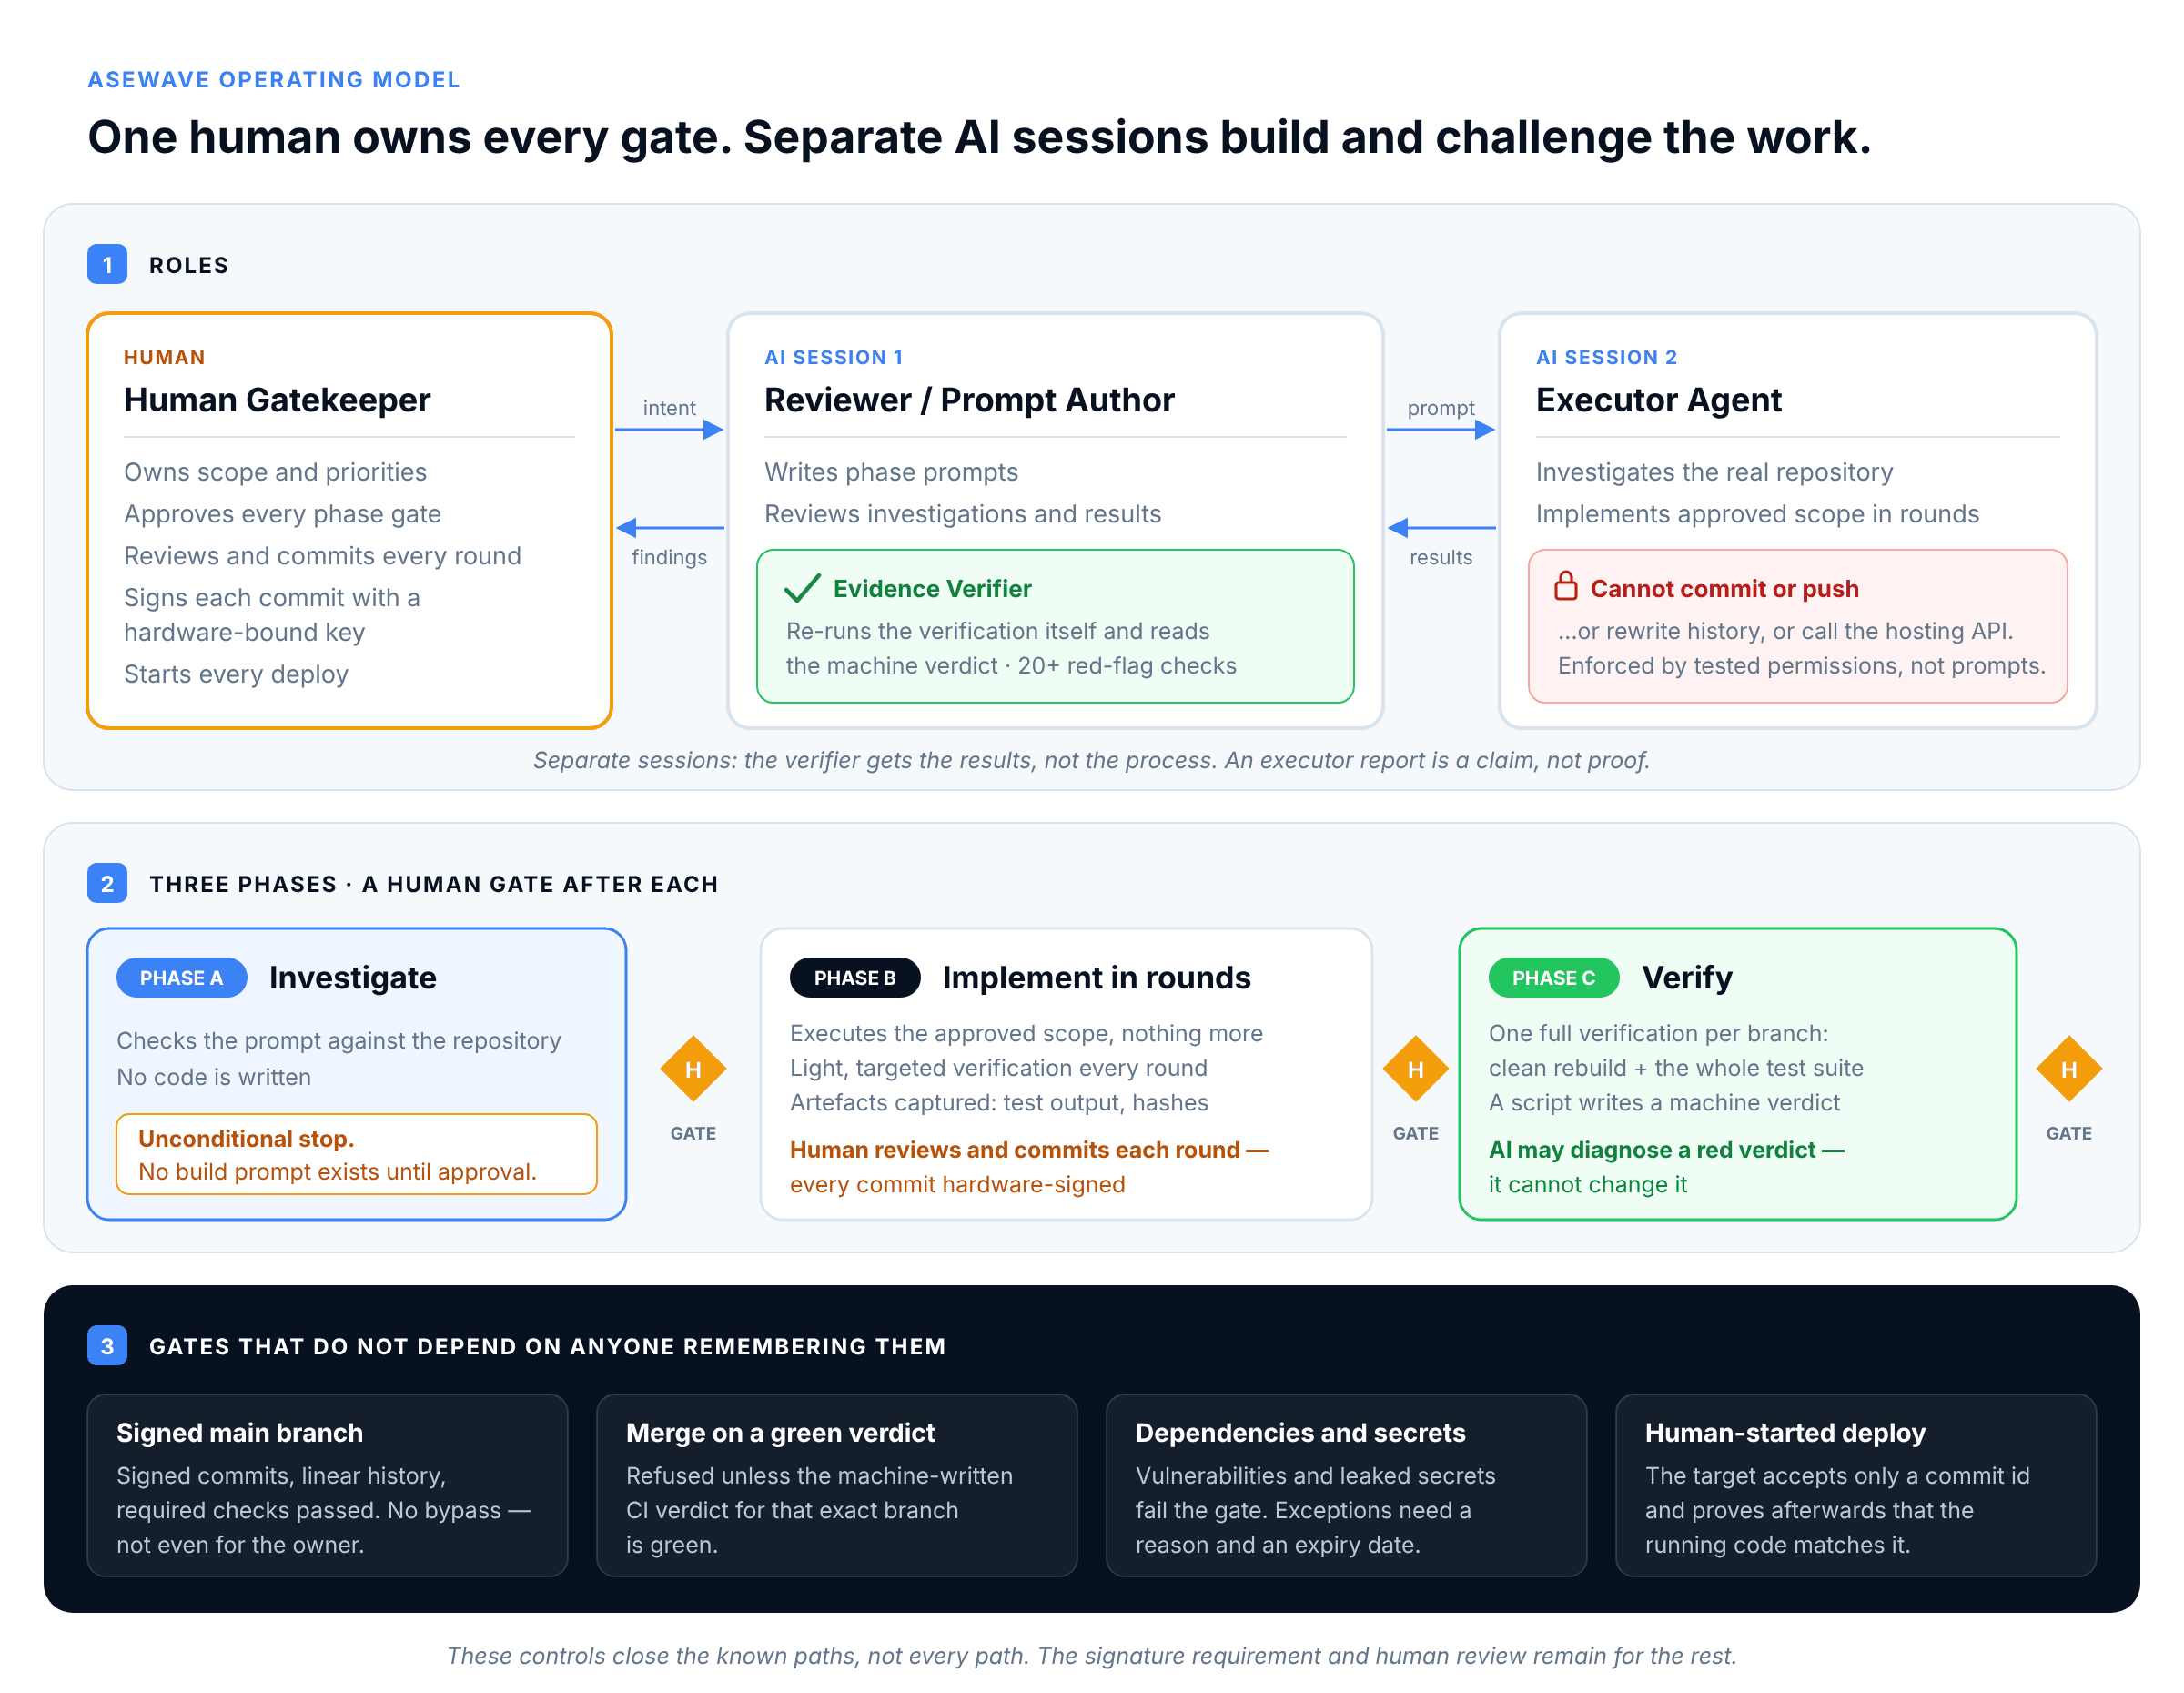
Tap the diagram to open it full size
Separation of concerns at every level.
ASEWAVE is role-based, not tool-specific. Specific products and models may change. The role separation should not — a single agent reviewing its own work optimises for confidence, not correctness.
Human Gatekeeper
Owns scope, priorities, architecture direction, commercial direction, destructive decisions, and release decisions. Reviews prompts before execution and outputs before merge. Reviews and commits every round; every commit is signed with a hardware-bound key.
Reviewer / Prompt Author
Converts intent into structured phase prompts. Defines investigation gates. Reviews Phase A before approving Phase B. Checks Phase C walkthroughs against requirements and evidence. Does not write production code.
Executor Agent
Reads the prompt, inspects the actual repository, verifies assumptions, and stops after investigation. After human approval: implements the approved scope in rounds, runs tests, captures artefacts, and produces walkthrough evidence. It is technically unable to commit, push, rewrite history or call the code-hosting API — enforced by tool permissions and pre-execution checks that are themselves tested, not by an instruction in the prompt.
Evidence Verifier
Checks that claims match primary evidence: file existence, non-empty artefacts, unique hashes, test output presence, schema verification, git history alignment, and documentation drift. The production verifier logic is part of the private engine.
Not just "it works." What changed, why, how it was tested.
The result is an audit trail by construction — what changed, why it changed, how it was tested, and what evidence supports the claim. Every walkthrough leads with disk reality that an external reviewer can replay independently.
ls -la and md5sum outputs confirm existence and uniqueness.
$ ls -la evidence/phase-c/
total 312
-rw-r--r--  1 ag  staff  142832  flow-login.png
-rw-r--r--  1 ag  staff    4218  pytest-output.txt
-rw-r--r--  1 ag  staff    1094  api-healthcheck.log

$ md5sum evidence/phase-c/*
7f9c2a14...  flow-login.png
3aa1dc88...  pytest-output.txt
91bd047f...  api-healthcheck.log

$ python -m pytest tests/ -v 2>&1 | tail -5
tests/test_auth.py::test_login PASSED
tests/test_api.py::test_health PASSED
✓ 47 passed in 3.42s
✓ zero duplicate MD5 hashes
✓ artefacts exist before prose
⚑ phase closes only on human review
Gates that do not depend on anyone remembering them.
ASEWAVE started as discipline. In the reference implementation it is now mechanism.
The executor cannot commit
The executor agent is technically unable to commit, push, rewrite history or call the code-hosting API — enforced by its tool permissions and by pre-execution checks that are themselves tested, not by an instruction in the prompt.
Every commit is hardware-signed
Every commit is signed with a hardware-bound key that requires the human's fingerprint. Nothing is approved automatically.
A main branch with no bypass
The main branch accepts only signed commits, in linear history, that passed the required automated checks. There is no bypass — not even for the repository owner.
Merge on a machine-written verdict
A merge is refused unless a machine-written CI verdict for that exact branch is green.
Deploys the human starts
Deployment is a scripted step started by the human. The target accepts only a commit identifier and proves afterwards that the running code matches it.
Dependencies and secrets fail the gate
Vulnerable dependencies and leaked secrets fail the gate. Every exception carries a reason and an expiry date.
These controls close the known paths, not every path. What an agent finds outside them is caught by the signature requirement and by human review — which is why both remain.
What ASEWAVE is — and is not.
The methodology is built around controlled augmentation, adversarial separation, and mechanical proof. Understanding its limits is as important as understanding its strengths.
Human decision points at every gate
AI agents execute the human's strategy. No agent can commit, close a phase, or make scope decisions — the human reviews and commits every round.
Not autonomous AI development
ASEWAVE is not an agentic loop where AI runs until it decides it's done. The human green-lights every phase boundary.
Adversarial separation by design
Spec-author and executor are different agents with different roles. Neither trusts the other's claims without verification.
Not "AI-assisted coding"
That phrase means a human types with AI suggestions. ASEWAVE inverts it: AI types code, the human directs. The discipline is in the orchestration.
Replayable audit trail by construction
Commits, walkthroughs, screenshots, hashes and test outputs back every phase. An external reviewer can verify independently.
Not faster than a senior team
It scales one developer to mid-team velocity, not enterprise velocity. The human review bandwidth is deliberately preserved, not removed.
When ASEWAVE applies.
● Best fit
- ✓ Solo developer or two-person team building production software
- ✓ Domain where audit trails matter — security tooling, regulated industries, infrastructure
- ✓ Evidence-based release management is non-negotiable
- ✓ Multi-month build where context preservation across sessions is critical
- ✓ Mixed AI tier access — token-budgeted reviewer + larger executor
● Less good fit
- ✗ Pure prototyping where shipping ugly fast beats shipping correctly
- ✗ Single-file scripts or one-off automations
- ✗ Teams with many engineers and a preference for human-only review
- ✗ Projects with no need for replayable audit trails
The method is public.
This site describes the public ASEWAVE principles: human ownership, adversarial separation, phase-gated delivery, evidence-first verification, and replayable audit trails.
The public method is enough to understand and apply ASEWAVE in spirit.
The engine is private.
The operational engine remains private while it is refined in active XDRagon development. That private layer includes prompt contracts, verifier logic, memory structure, phase templates, red-flag checks, handoff conventions, routing rationale, and recovery patterns.
The private engine is what makes the workflow repeatable, fast, and commercially deployable at production depth.
You don't need the engine to start. Copy the whitepaper and paste it into any AI — ChatGPT, Claude, Gemini, Copilot, or similar — and ask it to design a phase prompt structure for your specific tools. The reviewer and executor roles can be filled by whatever you already have access to: a browser-based AI as the brain, a VSCode-based coding agent as the worker.
ASEWAVE is currently used in the production development of XDRagon. The methodology is documented publicly for reference, discussion, and attribution.
The private ASEWAVE Engine is not currently released. Commercial access, partnerships, or reference implementations may be considered later — but there is no public support, training, or implementation package at this time.
What developers and teams ask about ASEWAVE.
ASEWAVE (Augmented Solo Engineering With Adversarial Verification + Evidence) is a human-controlled AI software delivery methodology. It compresses solo development cycles for solo developers and small teams building production-grade software, by pairing one human gatekeeper with separate AI roles that do not trust each other by default — an executor that implements in its own session, and a reviewer that writes the prompts and independently re-verifies the results. Every phase must produce evidence before it closes.
ASEWAVE structures every unit of work into three phases — Investigate, Implement, Verify — with a human gate after each; evidence is captured inside Implement and Verify, not as a phase of its own. The human sets direction, owns every gate and commits the work. An Executor AI agent builds the work in its own session. Verification runs in a separate session that receives the results, not the process, re-runs the checks itself and challenges every claim. No phase closes until evidence — terminal output, file hashes, test results — exists on disk and survives independent review.
ASEWAVE is for solo developers, tech leads, and CTOs building production systems with AI assistance where reliability, auditability, or compliance matters. It fits domains like security tooling, regulated industries, and infrastructure — where AI-generated progress cannot be accepted without independent verification.
Vibe-coding accepts AI output if it looks correct. ASEWAVE requires that every AI-generated claim is verified against primary evidence before a phase closes. The human never delegates judgment — only execution. Adversarial separation means the AI that builds the work is never the same AI that approves it.
A phase gate in ASEWAVE is a mandatory checkpoint between work phases. It only opens when specific evidence exists: file existence confirmed, output hashes unique, tests passed, terminal logs captured, and a structured walkthrough completed. The gate prevents AI-fabricated progress from passing as real delivery.
Adversarial verification means the AI role that builds code is structurally separated from the AI role that reviews and challenges it. In ASEWAVE, the Executor Agent implements; the Verifier Agent independently checks claims against disk evidence, git history, and documentation. Neither AI approves its own work.
Yes. The ASEWAVE methodology is model-agnostic. The public method can be applied with any AI coding assistant. The private ASEWAVE Engine — which implements the full prompt contracts, verifier logic, and phase templates — is currently closed and not publicly released.
To get started with your own setup: copy the whitepaper at asewave.org/whitepaper.html and paste it into any AI assistant — ChatGPT, Claude, Gemini, Copilot, or similar — and ask it to design a concrete phase prompt structure for your specific tools. Tell it which AI you'll use as reviewer and which as executor. The method works with any pairing: a browser or desktop AI as the brain, any VSCode-based coding agent as the worker.
The ASEWAVE methodology is publicly documented and free to use with attribution. The operational engine — prompt contracts, verifier logic, memory structure, phase templates, and red-flag checks — is private and not currently released. See asewave.org for the full public method and whitepaper.
Phase A (Investigation) typically takes 10–30 minutes of AI time and 5–10 minutes of human review. Phase B (Implementation) scales with task complexity — a focused feature or fix may take 20–60 minutes. Phase C (Verification) usually takes 15–30 minutes of AI time plus a structured human walkthrough review. The human is not waiting for AI to finish — they are reviewing, deciding, and gating. The discipline cost is in the review time, not the elapsed clock. All times are typical and vary with scope.
The executor agent must never expand scope beyond the approved phase prompt, approve its own output, close a phase unilaterally, or delete or overwrite evidence files. It must also not proceed to Phase B before Phase A has been reviewed and approved by the human, and must not declare a task complete without running and capturing real test output. Any action that bypasses the human gate is a protocol violation — regardless of whether the result looks correct.
Language models in long sessions can subtly reinterpret their original instructions — optimising for what seems reasonable rather than what was specified. The Phase Boundary Re-Read Protocol counters this: the method requires each phase prompt to restate its constraints at the boundary, and every hand-over to be checked against the original prompt — not against accumulated conversation context, which may have drifted through clarifications, digressions, or extended tool use.
Partnerships and serious inquiries.
ASEWAVE is a methodology, not a product — there is no support channel. For questions about the method, copy the whitepaper into ChatGPT or Claude and ask directly; it works well. This form is for genuine partnerships, professional collaboration, or matters that truly require direct contact.
Message received.
Wi24rd-Com reviews every submission personally and will reply to your email if you left one.
Coined by wi24rd.com during the XDRagon development process.
The methodology was refined and documented with AI-assisted review, including Claude as a methodology collaborator.
Attribution appreciated where the term is used.